
Serverless applications: a basic overview and best practices provides the broader context. Local caching is one of the quickest ways to avoid repeated work in an AWS Lambda function. It’s also bounded by the execution environment that holds it. When a function scales out, each new environment starts with an empty local cache and may repeat the same downstream lookup.
A centralized cache gives those environments a shared copy. That distinction matters when you want to reduce duplicate reads across a horizontally scaled application or move data through a workflow whose payloads have size limits. Local and centralized caches can both help; the data’s required scope determines which one fits.
This shared-cache pattern was missing from my list of 9 ways to optimize serverless applications. It also illustrates why different cache types solve different problems.
Historical context: This post describes AWS and Momento service behavior as of October 2022. Current documentation records several significant changes. EventBridge PutEvents now allows a request of up to 1 MB, and Momento Cache lists a 5 MB item limit. Lambda Managed Instances can process concurrent invocations in one execution environment, while ElastiCache now offers a serverless deployment option. Momento Cache also now has Cluster, Flex, and Serverless variants. The original limits and comparisons remain below as a historical snapshot.
A local cache stops at the execution-environment boundary
To see where local caching helps—and where it stops—look at how Lambda handled demand when this post was published.
When a Lambda function was invoked, it created an execution environment: the container that initialized connections and ran the function’s code. After the code finished, the environment stayed alive for a period of time in anticipation of another invocation. A subsequent invocation could skip initialization and reuse data stored outside the main function handler.
AWS recommended taking advantage of that reuse:
Take advantage of execution environment reuse to improve the performance of your function. Initialize SDK clients and database connections outside of the function handler, and cache static assets locally in the
/tmpdirectory. Subsequent invocations processed by the same instance of your function can reuse these resources. This saves cost by reducing function run time.
At the time, a Lambda execution environment responded to one request at a time. If another request arrived while an environment was running code, Lambda initialized another environment to meet the demand.
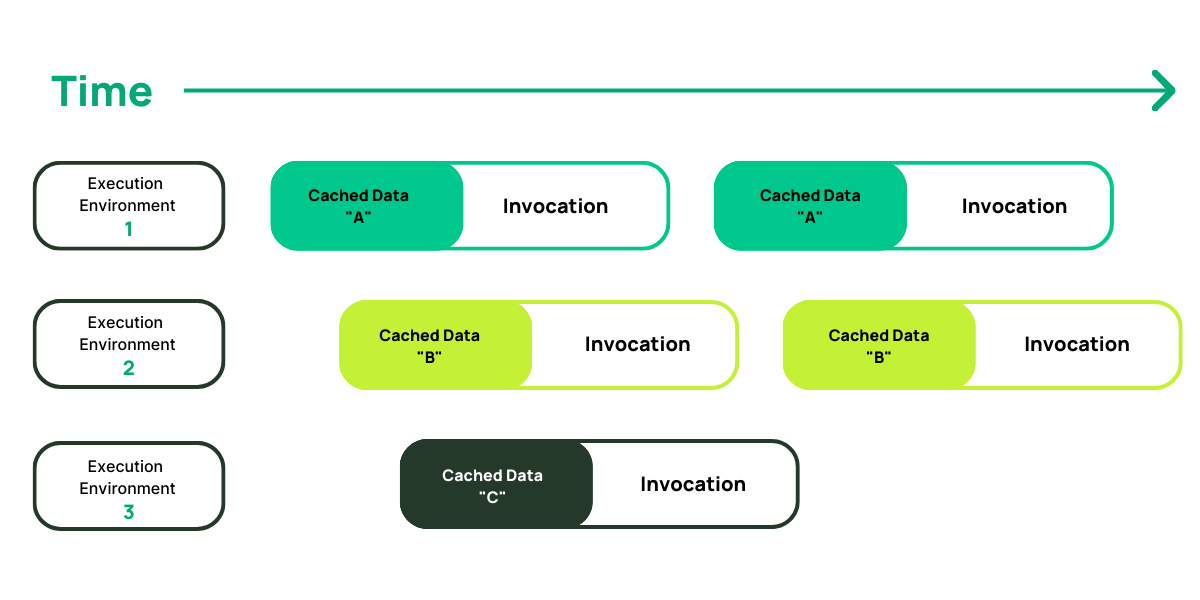
The example above has 5 invocations across 3 execution environments. Each environment owns its locally cached data, and that data disappears when the environment shuts down.
If all 5 invocations look up the same S3 object, the first invocation in each environment misses its local cache. That creates 3 copies of the same data and 3 initial S3 lookups. A remote cache can instead give every environment one shared place to retrieve that value.
Now imagine a Lambda function that loads product metadata and thumbnails. A heavily anticipated product comes online, and a wave of traffic causes the function to initialize thousands of execution environments. Each new environment must load the same data before it can cache that data locally. Those repeated SDK calls add lookup cost and work.
Later invocations in each warm environment can still benefit from the local copy. Local caching therefore remains useful for SDK clients, database connections, and data reused within one environment. It doesn’t share a cached value across the full application.
A centralized cache shares work across environments
A remote, centralized cache changes the scope. Every execution environment—and other services in the backend—can use the same cached value.
That shared state requires planning. Review what to consider before adding a cache. The architecture still needs an intentional strategy for what it caches, how long values live, and what happens on a miss.
One option is read-aside caching. The application checks the central cache before fetching data from its persistent datastore. A hit returns the cached value. A miss loads the value from a datastore such as DynamoDB, returns it, and populates the cache for later requests.
The mechanism reduces duplicate downstream reads when separate execution environments request the same reusable data. The cache does not replace the system of record; it creates a shared, temporary copy.
Cache keys can carry work across payload limits
A centralized cache can also serve as a temporary handoff between services. Consider a Step Functions workflow that loads data from multiple sources, consolidates it, performs transformations and validation, and finally saves the result to DynamoDB.
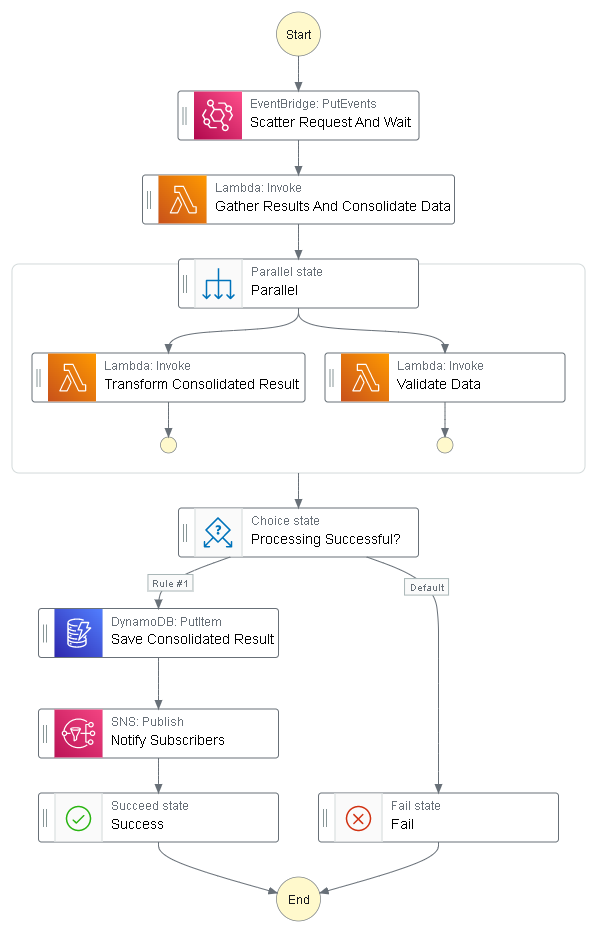
In 2022, the consolidated data could quickly cross the 256 KB Step Functions state-data limit. The workflow also gathered data from microservices through EventBridge, which then had a maximum message size of 256 KB.
Those limits prevented the workflow from sending the full data back and forth in each event or keeping it in the Step Functions execution context. Instead, we could store the data temporarily in a central cache and pass its cache key through the workflow. Each service would exchange a small reference while reading and updating the shared value.
Momento’s soft item-size limit was 1 MB when this post appeared. That gave the example four times the state machine’s 256 KB payload capacity, and the team could approve a higher limit on request.
The traditional alternative was to store the item in S3 and load it on demand in each Lambda function. Microservices could share access to the object through a presigned URL. The central-cache approach instead gave the services one temporary handoff location with the response-time behavior measured in this Lambda example.
Choose the cache scope that matches the job
Local caching and centralized caching solve different parts of a serverless application. Keep reusable clients, connections, and environment-local values close to the function. Use a central cache when multiple execution environments or services need the same temporary data.
In the 2022 service landscape, DAX and ElastiCache offered caching through provisioned clusters with management, failover, and resource-pricing decisions. Momento’s original serverless cache offered a remote, automatically scaling alternative. That contrast informed the recommendation in this article; the historical note above identifies the major ways today’s options differ.
The durable architecture question is narrower than “Does this application need a cache?” Ask who needs to share the value, how long it should survive, and whether the cache is reducing downstream reads or carrying a temporary payload. The answers tell you whether the cache belongs inside one execution environment or at the center of the application.
See the current Momento Cache (Serverless) getting-started guide to try the shared-cache pattern.