Alright, maybe “dark art” is a step too far, but multi-tenancy is hard to get right. The efficiencies of a multi-tenant system are tempting. The risk is that weak isolation lets one tenant hurt availability and performance for everyone else—the noisy neighbor problem.
The recently published DynamoDB paper has been widely covered. If you haven’t read it, I recommend the summaries from Alex DeBrie and Marc Brooker.
I want to focus on one of the paper’s hidden gems: how a mission-critical service like DynamoDB handles multi-tenancy. The paper shows both why teams build multi-tenant systems and how they can protect customers from noisy neighbors.
Why multi-tenancy is worth the risk
Multi-tenancy fuels innovation. Single-tenant systems typically operate at a smaller scale, so operators have less incentive to invest beyond the effort required to sustain them. As a multi-tenant system’s customer base grows, common patterns emerge. It becomes easier to justify investments that benefit every user.
On DynamoDB, for instance, that scale fueled innovations such as On-Demand provisioning. Each customer could handle bursts without provisioning for them in advance.
Shared capacity improves the economics
Marc Brooker says it best:
Multi-tenancy is a big economic and efficiency win, and tends to allow much higher utilization of resources. That’s good for sustainability. It’s also good for availability, because there’s less dynamic range in the workload the system needs to deal with.
Allen Helton’s post on multi-tenancy offers another perspective on the model.
The economic argument starts with provisioning. Single-tenant systems are usually overprovisioned, underprovisioned, or both: they carry excess capacity for average load but still cannot handle every burst.
A multi-tenant system consolidates resources into a shared pool, and its operators work to improve utilization. Consider 100 individual caches. Each single-tenant cache provisions enough capacity for its own peak, so total provisioned capacity must cover the sum of all 100 peaks. A multi-tenant system can provision for the aggregate peak, which is meaningfully smaller because those individual peaks do not all occur at once. The effect grows with the number of caches in the pool.
Scale also changes which optimizations are worth making. Operators of large multi-tenant systems spend their mornings thinking about cost, scale, and availability. A cost optimization can take months. That effort may be difficult to justify before a system reaches sufficient scale, especially when a manual change such as scaling down a cache cluster adds operational risk.
Consider a customer running a three-instance cache.r5.xlarge ElastiCache cluster for $948 per month. The cluster has 26 GB of RAM, four vCPUs, and can handle more than 100K requests per second (RPS). If the team uses only 5 GB of RAM or peaks at 10K RPS, it could move to a smaller instance. A newer instance type, ideally with Graviton, could improve performance and reduce cost further.
But at $12K per year, is that saving worth a sprint and the operational risk of resizing the cluster? Probably not. Most teams are understaffed, and they have easier ways to save money.
Now imagine a 3,000-node cluster that costs $12M per year. At that scale, it makes sense to dedicate an engineer to right-sizing the fleet, automate capacity changes for new peaks, and instrument deployments deeply.
Operators can also oversubscribe a multi-tenant system once they have enough scale and data. Banks, the electric grid, and internet service providers all rely on this idea.
The Firecracker paper from the AWS Lambda team describes oversubscription as a statistical bet:
Oversubscription is fundamentally a statistical bet … We set some compliance goal X (e.g., 99.99%), so that functions are able to get all the resources they need with no contention X% of the time … Keeping these workloads uncorrelated requires that they are unrelated: multiple workloads from the same application, and to an extent from the same customer or industry, behave as a single workload for these purposes.
DynamoDB uses that statistical bet to offer different economics from a single-tenant system with idle resources:
DynamoDB employs a multi-tenant architecture. DynamoDB stores data from different customers on the same physical machines to ensure high utilization of resources, enabling us to pass the cost savings to our customers.
Operators learn scaling lessons once
Multi-tenant systems also have better scaling properties. Teams encounter many lessons as they grow to 100-node clusters, and those lessons often arrive one outage at a time. They require extensive benchmarking, instrumentation, characterization, and tuning.
A customer of a large multi-tenant system such as DynamoDB does not have to learn each lesson alone. A 100-partition DynamoDB table may span hundreds of nodes behind the scenes, but that scale is routine within the broader fleet:
DynamoDB achieves boundless scale for tables. There are no predefined limits for the amount of data each table can store. Tables grow elastically to meet the demand of the customers’ applications. DynamoDB is designed to scale the resources dedicated to a table from several servers to many thousands as needed. DynamoDB spreads an application’s data across more servers as the amount of data storage and the demand for throughput requirements grow.
Whatever scale you plan to send to the service, it has likely handled something larger for another customer or for customers in aggregate.
Warm pools make capacity available faster
Well-built multi-tenant systems can use warm pooling to handle a new customer’s burst or an existing customer’s spike. The system keeps excess capacity ready to absorb the extra load.
Warm capacity is technically inefficient, but scale gives operators enough data to tune it. Picture the empty seats on a public bus. A bus at 50% utilization is still more efficient than the empty seats across individual cars, including the cars that are not on the road. Much of Uber’s innovation centers on improving utilization across the car ecosystem.
With warm pooling, a multi-tenant system can provision capacity almost instantly. AWS Lambda is a useful example: its warm pools absorb spikes and give a request immediate access to a function unless the workload is massive or extraordinarily spiky.
Autoscaled EC2 capacity takes longer to arrive. The system must detect the spike, determine that it is underprovisioned, start new instances, wait for them to boot, add them to the load balancer, and begin routing traffic to them. That process can take minutes. Lambda has already combined automation, warm pooling, and judicious oversubscription to provide the burst efficiently.
Predictable limits improve availability
The final benefit is availability. For a cache, I include predictable performance and the ability to handle usage spikes in that definition.
Operators of large multi-tenant services invest in deep instrumentation and carefully rehearsed operations. Their systems are well characterized, have published limits, and tend to fail in more predictable ways. Because of availability bias, people can interpret those documented limits and failure modes as evidence that the systems are less available. Self-managed systems may simply fail in less familiar ways.
For example, DynamoDB has a published limit of 1,000 writes per second for a single 1 KB object and a maximum object size of 400 KB, which can be written only 2.5 times per second. Redis does not have those same limits and can likely handle much higher throughput on a single key. But if you store 512 MB objects or push hot keys, the point where the service tips over may vary from day to day.
DynamoDB instead emphasizes predictability. Figures 5 and 6 in the paper show similar tail latencies across loads from 100K operations per second (OPS) to 1M OPS. When readers asked why the axes were not labeled, the answer was that the specific latency mattered less than consistent p99 latency at every scale. From the client’s perspective, performance was indistinguishable at 100K, 250K, 500K, and 1M OPS.
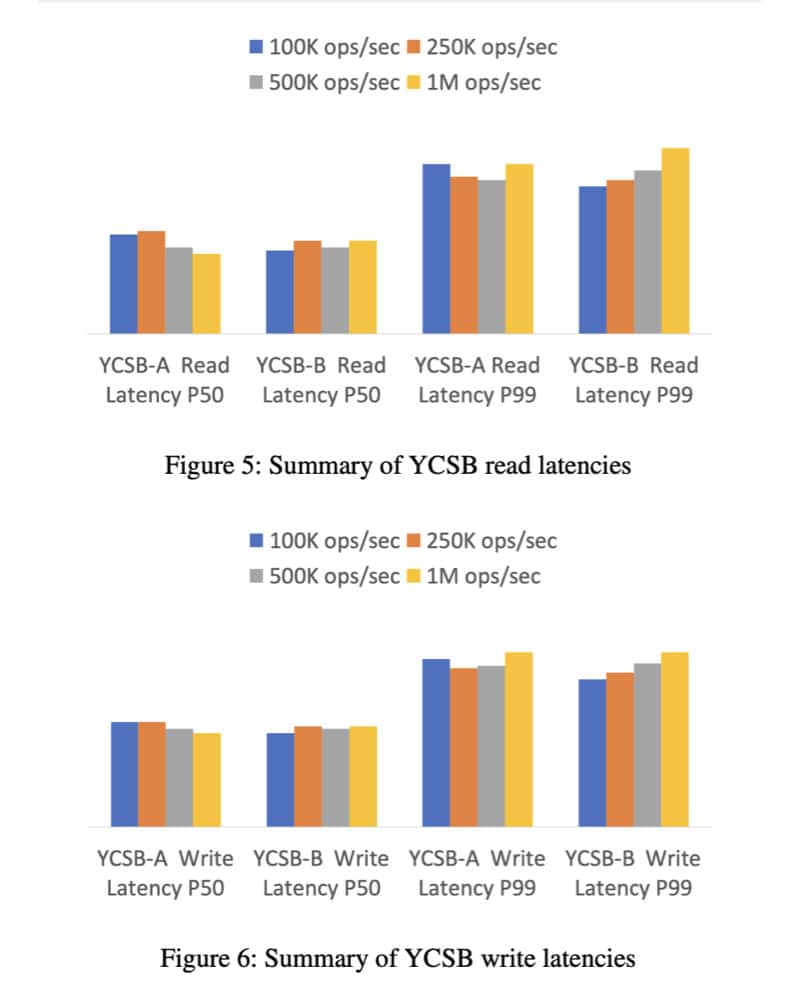
The lack of variability becomes more interesting in a multi-tenant test. The test likely ran against a DynamoDB production fleet full of spiky workloads. The DynamoDB team could run 1M OPS without affecting fellow tenants, and the other tenants did not affect the test load. You can reproduce the test on DynamoDB without speaking to an engineer and get the same results.
Noisy neighbors are the real risk
If multi-tenancy offers these benefits, why do we not see more of it? The answer is noisy neighbors.
One tenant can take more than its fair share of resources and hurt the performance and availability of others. A successful multi-tenant system therefore needs isolation and prioritization when the shared system is under pressure.
Single-tenant systems can suffer from the same problem. A supposedly single-tenant ElastiCache Redis cluster may serve many teammates or microservices. One rogue microservice can affect the entire cluster. A 10 MB object from one service can drive up tail latency while another service runs scans.
Multi-tenant systems address these common failure modes with deeper instrumentation and deliberate procedures. The rest of the DynamoDB paper shows how those protections work.
DynamoDB’s building blocks for multi-tenancy
Availability is DynamoDB’s key goal, including predictable request latency at any scale. That goal depends on three building blocks:
- Isolation protects customers from each other.
- Fairness prioritizes customers when the system is under pressure.
- Resource management keeps enough capacity available and uses it well.
A DynamoDB table consists of partitions on storage nodes. Each storage node holds partition replicas from many tables and accounts. Because those partitions are colocated, DynamoDB must isolate them at the partition level. Otherwise, one partition could consume all the node’s resources and starve other customers.
Load shedding and spreading protect each node
Large distributed systems, including caches, can develop a hot shard, also called a hot partition. One node receives an overwhelming share of the fleet’s load. Teams often respond by doubling the fleet to spread the load further. More generally, if load is uneven across nodes, the system must grow in proportion to that imbalance.
DynamoDB improves utilization by spreading load across storage nodes. Its autoadmin service acts as the system’s central nervous system:
The autoadmin service is built to be the central nervous system of DynamoDB. It is responsible for fleet health, partition health, scaling of tables, and execution of all control plane requests. The service continuously monitors the health of all the partitions and replaces any replicas deemed unhealthy (slow or not responsive or being hosted on bad hardware).
Autoadmin coordinates changes across the fleet. That centralization lets DynamoDB monitor continuously while limiting the churn that could occur if many nodes made conflicting decisions.
Storage nodes also monitor their own utilization. When a node crosses a configurable threshold, it informs autoadmin and proposes partition replicas to move. Autoadmin knows the utilization of other storage nodes and can find new homes for those replicas, presumably on underutilized nodes. Continuous monitoring keeps the load spread as each partition’s usage changes:
In case the throughput is beyond a threshold percentage of the maximum capacity of the node, it reports to the autoadmin service a list of candidate partition replicas to move from the current node.
This technique lets partitions burst beyond their provisioned or allocated capacity. It also moves load away from storage nodes before they become overwhelmed.
Fairness matters when capacity is scarce
Sufficient capacity and evenly distributed load make a fair experience automatic. Fairness matters most when the system is under pressure. A DynamoDB storage node serves requests while it has enough capacity, improving utilization for customers with provisioned IOPS and those using on-demand tables.
That approach requires several complementary mechanisms: controlled bursting, prioritization, and throttling.
First, controlled bursting limits the maximum IOPS that one partition can consume on a node. The limit reduces the partition’s blast radius and makes capacity planning more effective.
Second, bursts are available only to partitions on nodes with unused capacity:
DynamoDB still maintained workload isolation by ensuring that a partition could only burst if there was unused throughput at the node level.
DynamoDB has provisioned and on-demand tables. Provisioned IOPS are spread across partitions, but those partitions can burst beyond their provisioned IOPS. DynamoDB on-demand tables adapt rapidly to customer workloads and remove capacity management from the customer. They are analogous to EC2 Spot Instances, but tight capacity management and load spreading let the DynamoDB team offer an almost indistinguishable experience for on-demand tables.
Finally, DynamoDB prioritizes requests to balance utilization and isolation. When a storage node is under pressure, partitions with provisioned IOPS take priority over partitions that are bursting above their allocation.
Proactive load shedding usually makes this condition short-lived. The stressed node works with autoadmin to spread the load. When utilization is low, each partition can burst up to 3,000 IOPS regardless of its provisioned IOPS. The team tunes that statistical bet against its service-level objectives: higher utilization increases the risk of noisy-neighbor effects, while lower utilization erodes efficiency. Most customers never notice variability, which suggests the isolation works.
Global admission control enforces table-level limits
In DynamoDB’s early days, storage nodes enforced IOPS limits at the partition level. Customers with IOPS distributed unevenly across partitions could see throttling even while using only a small portion of their total provisioned IOPS.
DynamoDB addressed that problem with Global Admission Control (GAC), which enforces IOPS at the table level instead of the partition level.
Requests travel through a stateless router layer that forwards operations to the relevant storage nodes. The request routers know how many IOPS each table has. They connect to a fleet of GAC nodes and track the token bucket for an assigned table. A table that consumes too much capacity can then be throttled at the request router before its requests reach a storage node.
The storage-node token buckets remain as defense in depth. They provide a second layer of protection: if the request routers admit more traffic than a node can handle, the storage node can still isolate partitions and prioritize those below the burst threshold.
Isolation turns efficiency into reliability
DynamoDB is one of the best examples of multi-tenancy fueling innovation. Applying multi-tenancy at scale while preserving mission-critical availability required the team to improve utilization, cost, and performance. Customers received those benefits without becoming distributed systems experts, and the system continued to evolve underneath them.
No single protection makes this work. DynamoDB combines load shedding, node- and table-level throttling, and best-effort bursts. Together, those mechanisms support a reliable, mission-critical service for Amazon retail, most AWS control planes, and, consequently, most AWS customers.
That is the tradeoff at the heart of multi-tenancy. A well-built multi-tenant system can offer better economics, availability, and experience than a single-tenant system. But it earns those advantages only by treating isolation, fairness, and resource management as core design problems.
We are embracing multi-tenancy at Momento for the same reason. We already operate at a scale where deep investment in resource and performance optimization is worthwhile, and we are eager to keep improving the experience for our customers.
Have questions, corrections, or ideas for a follow-up? Send them to @ksshams.