My earlier AWS experiment made me wonder whether caching would have a similar effect after I moved the same small API to Google Cloud Platform (GCP). For this test, I deployed the service on Cloud Run and kept user data in Firestore. Then I compared those reads with Momento Cache.
In this 2022 test, the p99 processing time for the single-read cached path fell from 433.2 ms to 6.0 ms—a reported 98% reduction. The six-read follower path fell from 4,610.0 ms to 14.1 ms. Those results came from one laptop-driven experiment, not a general performance guarantee.
The API under test
The demo models a social network in which each user has five followers. A frontend needs the current user’s record and the names of those followers.
One lookup
GET /usersmakes one call to Firestore.GET /cached-usersmakes one call to Momento.
The endpoints return a user record like this:
{
    "id": "1",
    "followers": [
      "26",
      "65",
      "49",
      "25",
      "6"
    ],
    "name": "Lazy Lion"
}
Six lookups
GET /followersmakes one Firestore call for the user, then five more Firestore calls to look up the follower names.GET /cached-followersmakes the same six lookups through Momento.
The second pair exposes the effect of waiting on a dependency several times during one API request.
Choosing a GCP stack
I was new to GCP after spending most of my career on AWS. To move the demo, I needed alternatives for its database, metrics, runtime, and infrastructure as code (IaC).
Firestore for the database
I started with the highly scientific approach of searching DuckDuckGo for “best GCP alternative to DynamoDB.” The results pointed me to Firestore as a NoSQL database, so I gave it a try.
Cloud Monitoring for metrics
On AWS, I had used aws-embedded-metrics to collect metrics through CloudWatch Logs. For GCP, I recorded custom metrics with Cloud Monitoring and its Node.js SDK.
Cloud Run for the runtime
Google Cloud offered Cloud Run, Cloud Functions, App Engine, and Compute Engine virtual machines. I didn’t want to manage operating systems and networks for this REST API, and I didn’t need to open the Kubernetes toolbox.
Cloud Functions was the closest match to the Lambda service I had used on AWS. I chose Cloud Run instead because I wanted to package the API as a container and make later cross-cloud experiments easier.
Pulumi for infrastructure as code
I’m a huge fan of IaC libraries. In 2022, I couldn’t imagine returning to editing YAML directly for all my platform work. I used the AWS Cloud Development Kit (CDK) and had previously tried CDK for Terraform on GCP. This time, Pulumi’s Cloud Run TypeScript example looked compact and readable.
I wanted the application code to stay organized enough that I could change its deployment tools and runtime without redesigning the service. The serverless API demo repository contains the full implementation.
Approximating the earlier runtime
I changed four settings in Pulumi’s Cloud Run service definition to approximate the Lambda environment from my earlier experiment:
- CPU: a
2000mlimit, or 2 vCPU, matching the target I associated with the earlier 2 GB Lambda configuration. - Memory:
2Giper container to match the Lambda memory setting. - Timeout: 15 seconds instead of the five-minute default.
- Container concurrency: one request at a time to resemble how Lambda assigns one request to a Firecracker microVM. Cloud Run used Knative. The concurrency setting made its request handling closer to the Lambda shape I wanted to test.
This was an approximation for the experiment, not proof that the two runtimes were equivalent. Here is the Pulumi configuration:
const service = new gcp.cloudrun.Service("ts-api-svc", {
   location,
   template: {
       spec: {
           timeoutSeconds: 15,
           containerConcurrency: 1,
           containers: [{
               envs: [
                   {
                       name: "RUNTIME",
                       value: "GCP"
                   },
                   {
                       name: "PROJECT_ID",
                       value: project
                   }
               ],
               image: myImage.imageName,
               resources: {
                   limits: {
                       cpu: "2000m",
                       memory: "2Gi",
                   },
               },
           }],
       },
   },
});
What the 2022 test measured
I generated basic load from my laptop with Locust. The API and Firestore ran in GCP’s us-east1 region, and I selected the us-east1 service location for Momento. From the Node.js container, I measured the overall API processing time and the time spent waiting on Momento or Firestore. I recorded both as custom Cloud Monitoring metrics.
The comparison used p99 latency: 99% of the measured requests completed at or below that value, while the slowest 1% took longer. The post preserves the region, endpoint call counts, container settings, and reported p99 results. It does not preserve the test duration, repetitions, software versions, request rate, or cache state. Treat this as a historical snapshot rather than a reproducible benchmark.
Reported p99 results
| Endpoint comparison | Firestore path (ms) | Cached path (ms) | Reported reduction |
|---|---|---|---|
/users vs. /cached-users | 433.2 | 6.0 | 98% |
/followers vs. /cached-followers | 4,610.0 | 14.1 | 99.7% |
These values are the rounded results reported in the 2022 post. They are not a service-level objective or a promise for other workloads.
For the single-read path, the captured chart shows the Firestore-backed /users request near 433 ms and the cached path near 6 ms. The vertical axis uses a logarithmic scale.
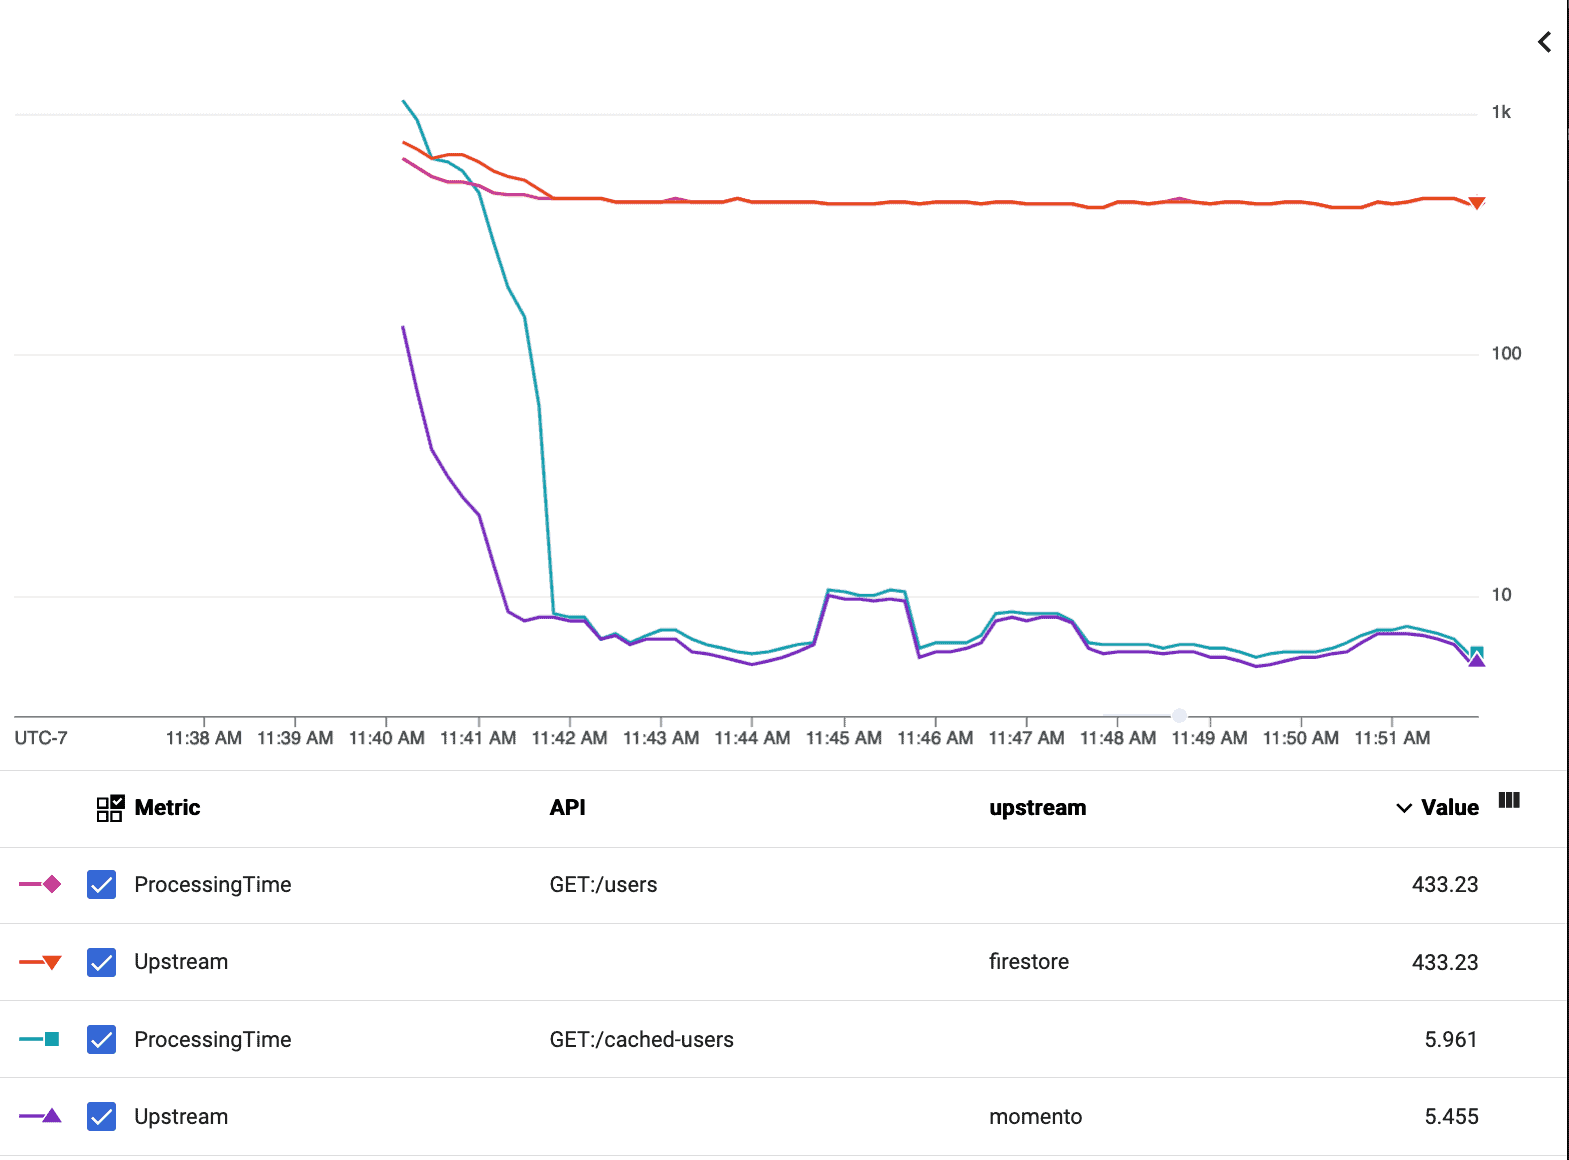
The follower path made six dependency calls per API request. Its reported p99 fell from 4,610.0 ms with Firestore to 14.1 ms with Momento, a 99.7% reduction in this test.
What I took away
The experiment showed me how quickly dependency latency can compound when one API request waits on several reads. In this setup, the cache-backed path changed the single-read p99 from hundreds of milliseconds to 6.0 ms and the six-read path from seconds to 14.1 ms.
It did not directly measure Cloud Run cost, user satisfaction, or system-wide scalability. Those outcomes depend on the production workload, cache hit rate, consistency requirements, failure behavior, and network path. I was still impressed by how quickly I could get the GCP version running, and the result gave me a concrete reason to test other runtimes and cache options.
If you want to reproduce or challenge the result, start with the serverless API demo and record the missing workload conditions alongside your measurements.