Fast averages can hide slow customer requests. At Momento, four practices help us expose those requests, evaluate improvements, and catch regressions before production.
Focus on tail latency, not the median or average
When building performance-sensitive software or services, it is tempting to advertise p50 or average latency. Those numbers typically look much better than p99 or p999. We often see tail latency at p99 or p999 reach 10 to 100 times the average.
A single-request p50 measurement does not represent the application experience when one action makes many backend calls. Modern applications sometimes make dozens of calls to the same backend, and customers must wait for the slowest one to respond. That fan-out increases the impact of tail latency. If cache tail latency exceeds database latency, the cache can defeat its own purpose.
Build a test harness for rapid evaluation
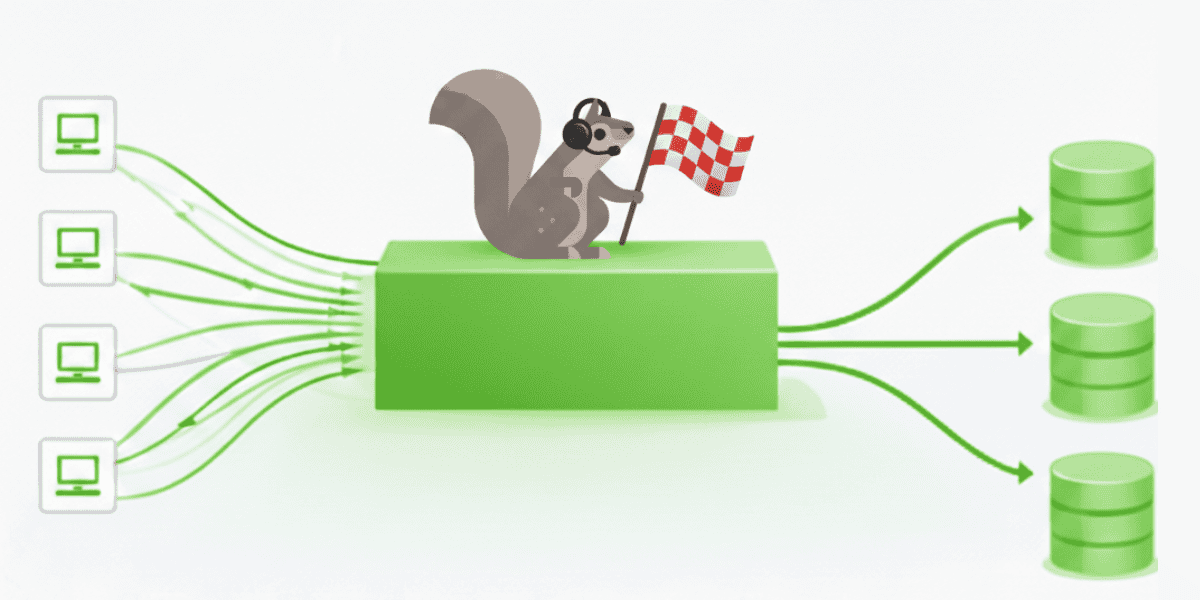
A solid test harness lets teams quickly evaluate a broad range of performance optimizations. At Twitter, Brian Martin built rpc-perf, a general-purpose RPC benchmarking tool used extensively to evaluate caching services there. It provides high-resolution latency metrics, waterfall visualizations, powerful test configurations, and support for protocols including Memcached and Redis.
We added Momento’s gRPC protocol support and OpenTelemetry integration to rpc-perf. This lets us visualize benchmark results in Grafana and Lightstep. Infrastructure as code lets us rapidly deploy a fleet of rpc-perf instances to send load at scale toward Momento. Our metrics provider aggregates the results and gives us immediate visibility into service-level changes.
We are also adding a performance qualification stage to our deployments. Its job is to qualify the performance impact of changes before they reach production.
Set service-level objectives for every component
A test needs a definition of success. We use service-level objectives (SLOs) to ground the outcomes we want from each test.
First, each component has a minimum SLO that it must meet before it can enter the service. This applies to changes such as new code or engine upgrades. Second, we set aspirational SLO milestones. Once we reach one, it becomes the new minimum.
This approach balances our pace of innovation with the iterative performance improvements we want to deliver over time.
Test performance continuously
Test harnesses and SLOs are useful for evaluating major updates or tuning. Every deployment, however minor, also carries a risk of degrading performance.
A performance or soak stage in the CI/CD pipeline helps keep regressions out of production. Performance canaries help detect regressions that still reach production.
Together, these practices make performance a continuous engineering discipline instead of an occasional benchmark. See how we applied them in our deep dive on optimizing Pelikan for Google’s Tau T2A VMs.